One cluster from many machines
Tensor Relay splits a model's layers across the machines in your cluster. Each peer contributes GPU memory and compute, and together they run what none could alone.
Your hardware, your models
Run open-weight models on hardware you already own. No cloud bill, no API keys. Inference runs only on the machines in your cluster.
Agentic coding, built in
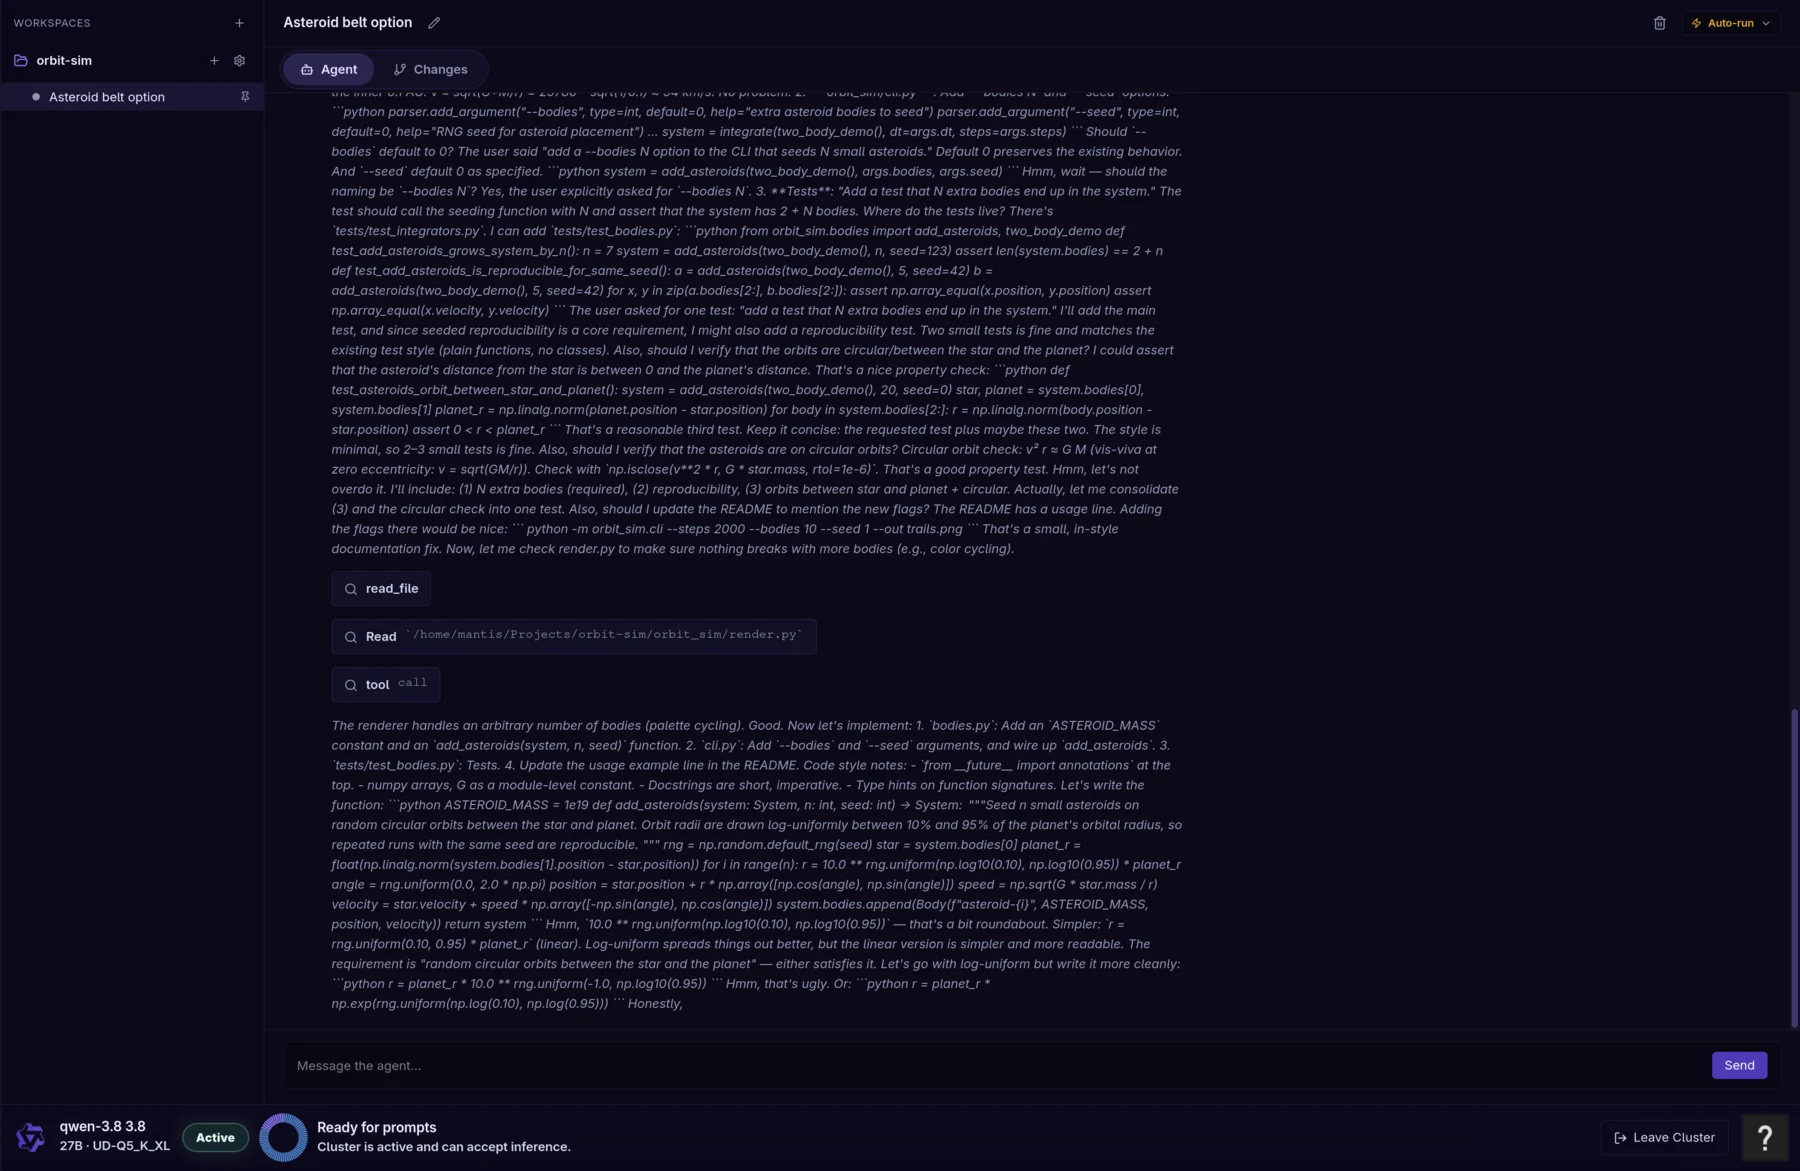
Point coding agents at your cluster: long-context code assistance and tool-calling agents, running on hardware you own.
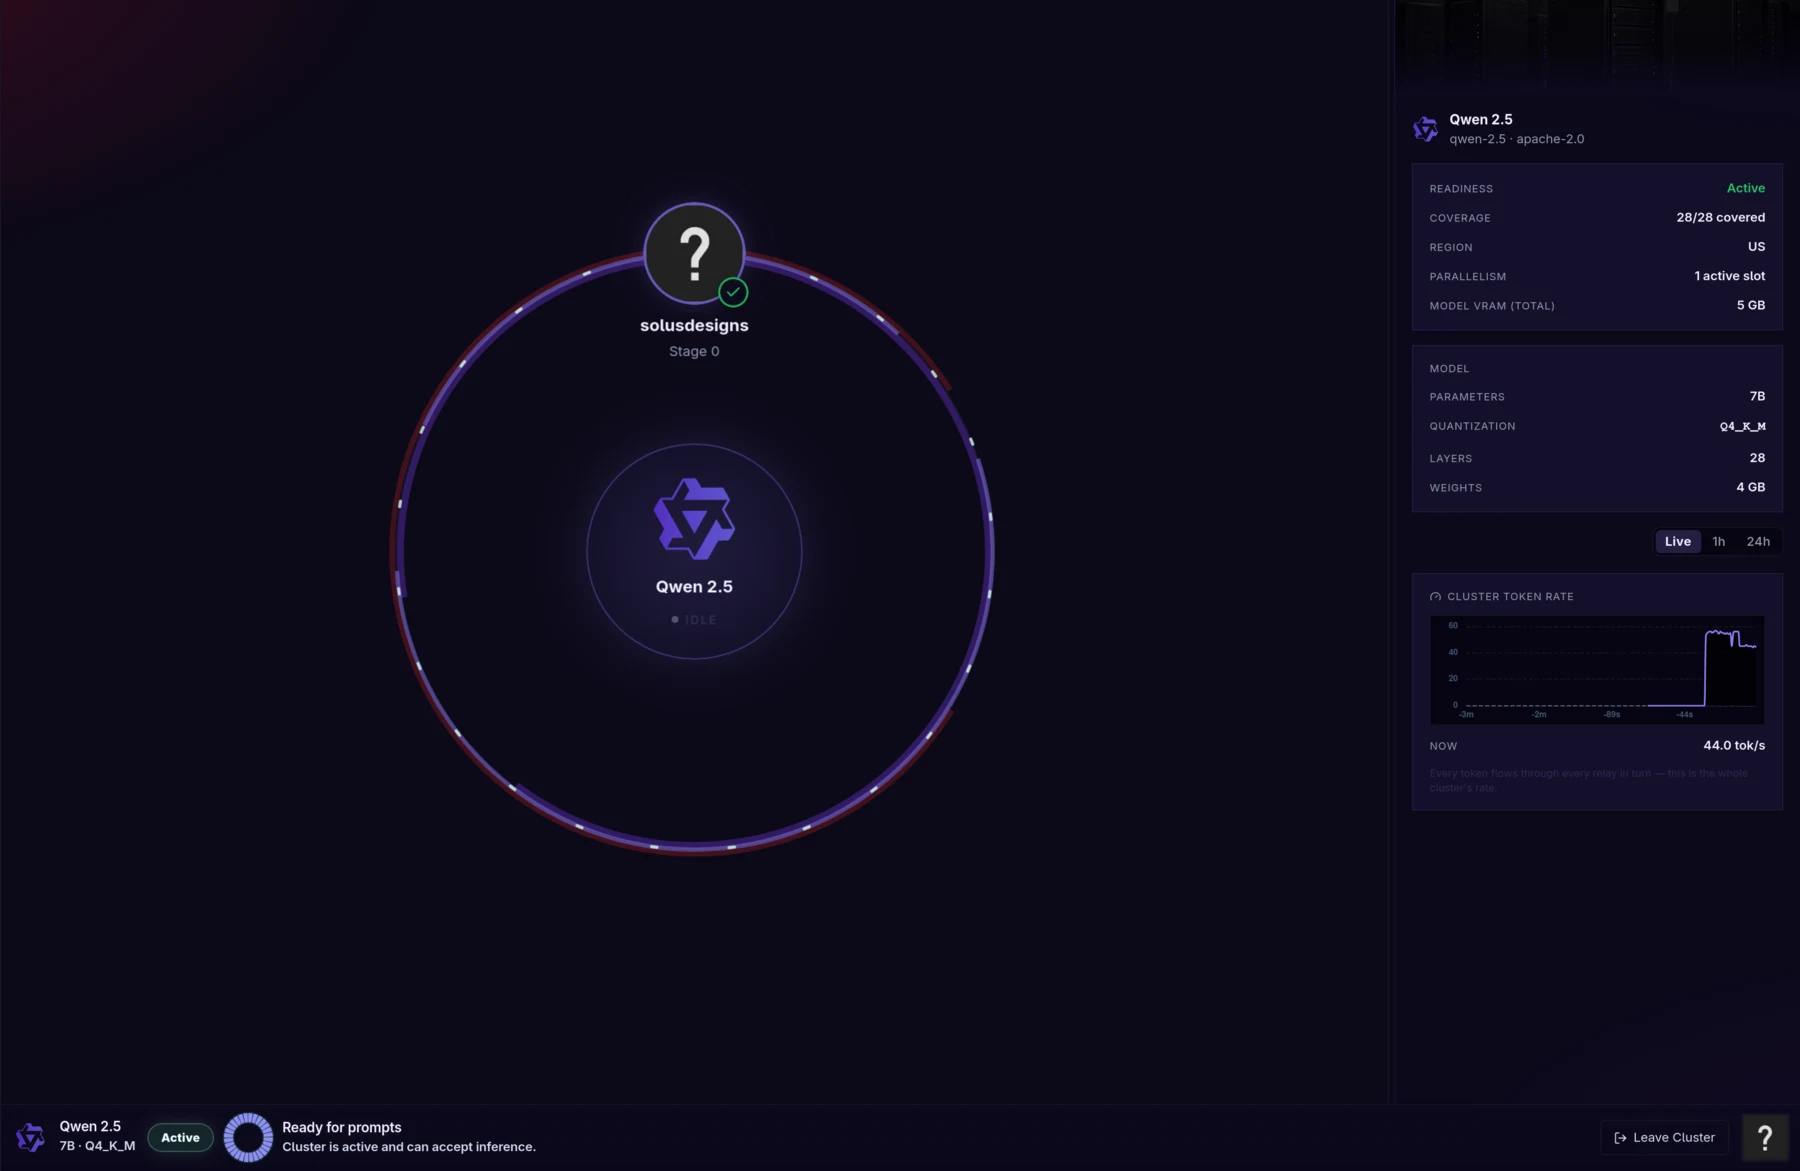
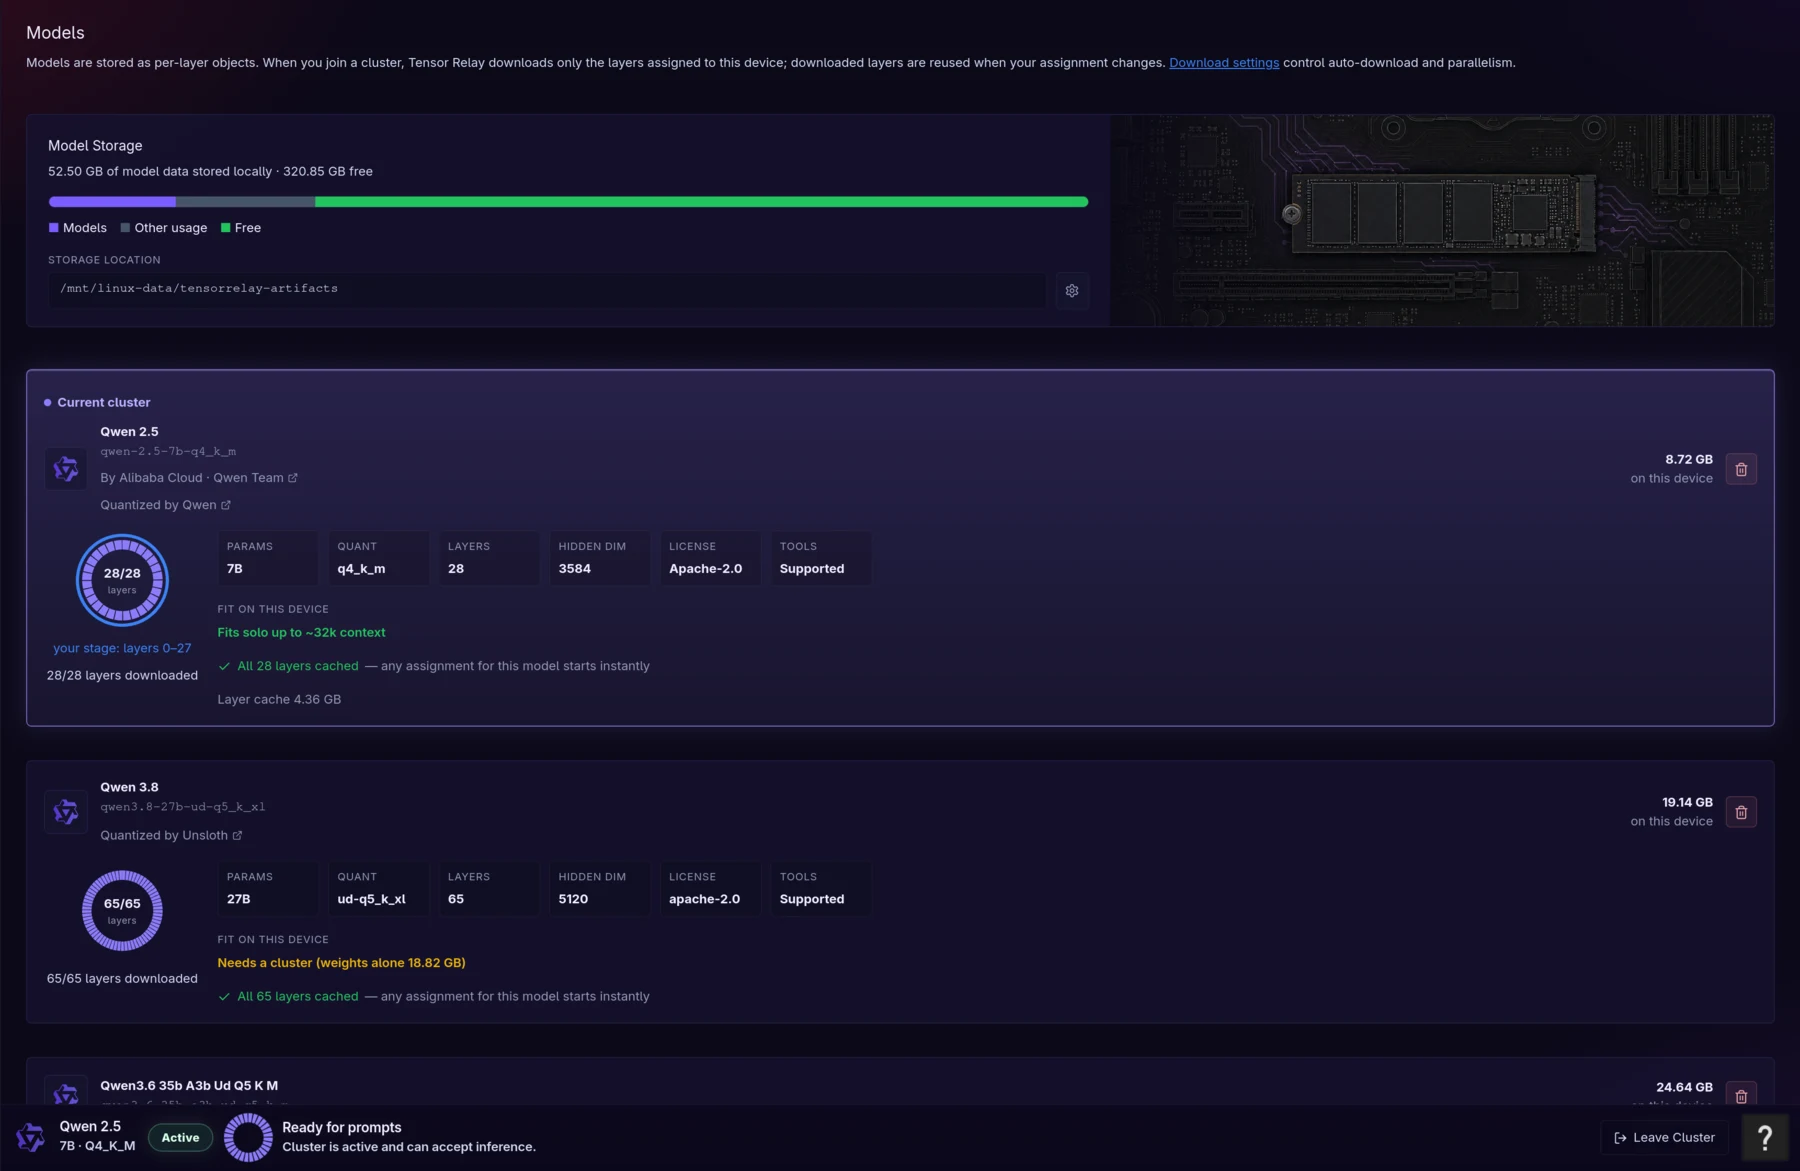
Cluster overview: who is holding which layers, latency across the ring, and the whole cluster's token rate.
Powerful frontier models produce stronger reasoning, richer code assistance, and more precise creative results because they carry more parameters, context, and learned capability. That extra quality usually means larger model weights and large VRAM requirements.
Tensor Relay makes those larger models practical by splitting work across participating machines. Each peer contributes GPU memory and compute, so a cluster can run models that would be difficult or impossible for average users.
Pool hardware with friends or public peers, and unlock access to high quality inference from home.
Tell us what you'd run it on. Invites go out in waves.